<- back to thoughts
Making it local, and catching broken bots
Log #6. No global shortcuts left in the safety check, and a swarm that notices its own faults.
october 2026 • robotics, swarms, fault tolerance, machine learning • 3 min read
project logMicrobots: programmable matteron /projectsentry 7 of 7
- 1Programmable Matteroctober 2026
- 2Dots and a flockoctober 2026
- 3Bots that build a shapeoctober 2026
- 4Going 3D: bots that never let gooctober 2026
- 51,000 bots in the browseroctober 2026
- 6From hand-written rules to a trained modeloctober 2026
- 7Making it local, and catching broken botsyou're here
My favourite demo so far: 902 bots build a curved arch where every layer steps in over the one below. Then a slice is cut out of the top, and the spares climb back up and fill it. Both sides are the same run, using Kuan's arm-link rules, drawn as microbot v1 on the left and as cubes on the right.
Two global shortcuts, gone
- Which cell to fill next. Before, the whole swarm agreed on one "layer being built". Now each cell decides for itself: it opens once the cell under it is filled and the cells nearby in the layer below are too. Every check looks only at nearby cells.
- Will anything fall? Before, every move was checked against the whole structure. Now each bot remembers one neighbour that holds it up. A bot can only move once everyone it's holding has switched to another holder whose chain still reaches the floor without it. Bots check that by asking up the chain, one neighbour at a time. It's more cautious, so builds are slower, but it has never dropped a bot in any test.
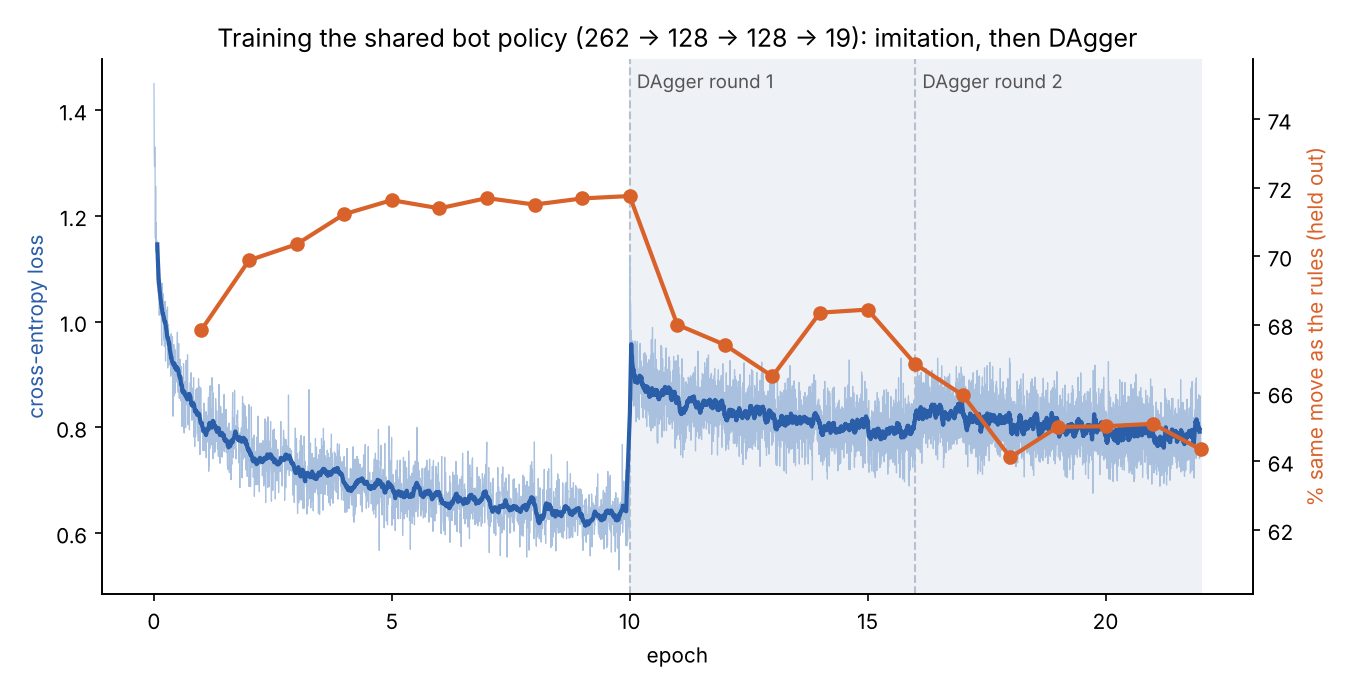
I retrained the model on the new rules, and it still builds every shape, every time.
The jam, mostly fixed
With Kuan's arm links and real connector strength, every build used to stall near the end: bots under the deck hung off each other in chains and nobody could let go first. Letting free bots swivel their arms in place, to link to more neighbours, plus having hanging bots back off toward the floor when stuck, took it from finishing 0 of 8 shapes to 7 of 8. The big arch still jams in most runs.
Broken bots
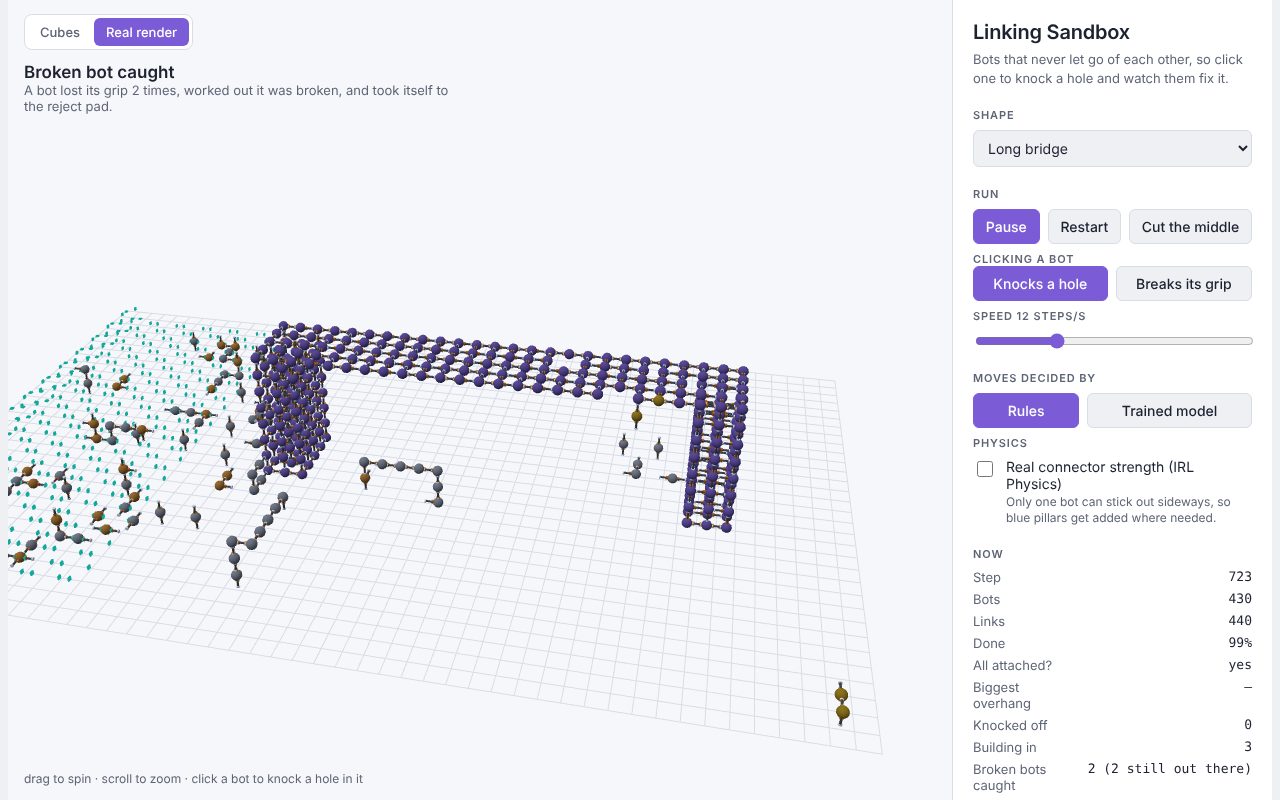
What happens if a bot's connector is faulty? It gets placed, falls off, gets replaced, and the swarm rebuilds the same spot forever. In the sandbox you can now click a bot to break its grip. Each bot counts its own falls, and after two it decides it's broken and takes itself to a reject pad. If different bots keep failing at the same spot instead, the spot is the problem, not the bot.
Things nobody programmed
Some of the best moments were behaviours that came out of simple rules on their own:
- Scaffolding: spares piled up under a deck and held it up while it was built.
- Cantilevers: half a cut bridge stays up, because every bot is still linked back to its leg.
- Pillar patterns: a simple arm rule made pillars alternate between holders and held bots.
And some were problems: the whole swarm moving as one blob, bots sealing themselves inside a dome, hanging chains nobody could let go of, one leg of an arch racing ahead of the other, and the trained model's "drift this way" shortcut.
What's next
Right now the model copies the rules, so at best it matches them. Next is reinforcement learning: let it try things and keep what earns more reward, to see if it can beat the rules, for example by building the long bridge with fewer support pillars than my hand-written planner's 245. First I'm fixing the simulation's remaining shortcuts (the compass is one), so anything it learns is learned honestly.
previous entry
From hand-written rules to a trained model
october 2026
that's the newest entry in this log, so far.